
What Is Latency In Ai And Llms Meaning Causes Fixes
Search results for fiber, optical network, data center, telecom power and outdoor communications infrastructure topics.
-
What to do if you have an AI server at home
I built a private AI server at home and now every device connectsOnce you've set everything up, you just need to enter your Tailscale IP address on any dev.
[PDF Version]
-
Reasons for AI Server Latency
AI latency comes from three sources: model computation, data transfer, and infrastructure overhead. Most applications can achieve sub-second responses with proper optimization. Latency is an architecture decision; design for it on day one, not after launch. Model routing (small model for simple tasks, large. AI latency isn't just a minor inconvenience—it's a productivity killer that disrupts workflow, breaks mental flow, and wastes AI latency isn't just a minor inconvenience—it's a productivity killer that disrupts workflow, breaks mental flow, and wastes valuable time during critical work moments. Push for speed without understanding those dependencies, and you do one of two things: overspend to brute-force performance, or simplify the system until it is faster. Data center operators must navigate the need for low-latency infrastructure to avoid failure in AI deployments. When it comes to AI, speed isn't a luxury. If latency creeps from 20 milliseconds to 200, that car doesn't just. Learn what latency in AI and LLMs means, why AI response time matters, what drives delays, and practical ways to reduce them.
[PDF Version]
-
What are some AI server providers
Top Five AI Server Companies for Data Centers and EnterprisesThis ABI Research competitive assessment ranks the top five AI server companies worldwide. AI.
[PDF Version]
-
AI Liquid-Cooled Switch
Exploring the Future of AI Networking: Liquid-Cooled Switches. Cisco is leading this innovation with ongoing R&D into direct-to-chip liquid-cooled switc.
[PDF Version]
-
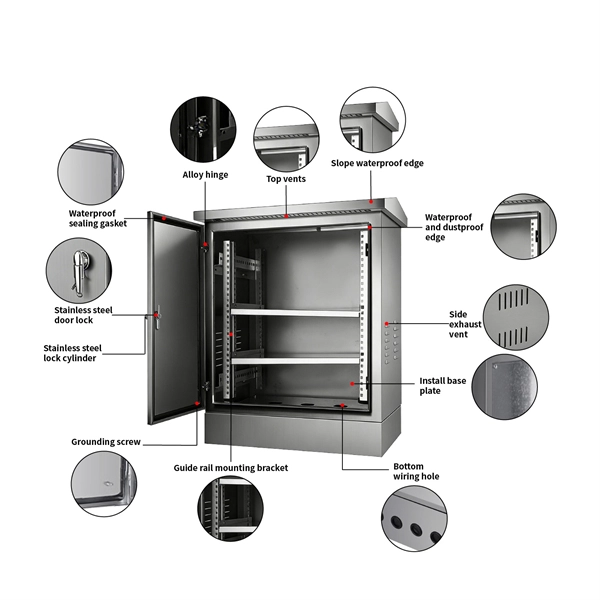
What does the indoor terminal box do
Terminal boxes connect, protect, and organize electrical wiring, ensuring safe and efficient operations. Whether you're working in a factory or setting up. A terminal box is an electrical enclosure equipped with organized terminal blocks designed for frequent access, testing, and modification of connections. It serves as a control interface or distribution point in industrial systems. Constructed from durable materials like glass-reinforced polyester (GRP), these boxes come in varying sizes. To ensure longevity, they often incorporate stainless steel screws for secure. home (FTTH) applications.
-
What is coherent fiber optic communication
A coherent optical fiber communication system leverages variable properties of light waves, including amplitude, phase, and polarization, to optimize the capacity of a fiber optic link. Far exceeding the limitations of traditional OOK, coherent optical transmission deploys tunable lasers and. With its ability to support exponential growth in data transmission across distance over the past 15+ years, coherent optical technology, or coherent optics, is a key contributor to today's modern communications infrastructure. A look back Before the advent of coherent optics, long-distance data. Coherent optical communication is a technology in the field of optical fiber communication. Each has unique principles, characteristics, and use cases.
[PDF Version]
-
What is multimode fiber used for
Single Mode vs. Multimode Fiber Optic Cables Multimode fiber (MMF) is an optical fiber designed to carry multiple light propagation paths—or modes—simultan.
[PDF Version]
-
What does FQH represent for cable trays
FQH fire-resistant cable tray-Yichuang-Efficient power distribution The FQH series cable tray has excellent heat insulation, fire resistance, corrosion res.
[PDF Version]
-
What is the focal length of the beam splitter in millimeters
In its most common form, a cube, a beam splitter is made from two triangular glass which are glued together at their base using polyester,, or urethane-based adhesives. (Before these synthetic, natural ones were used, e.g.) The thickness of the resin layer is adjusted such that (for a certain ) half of the light incident through one "port" (i.e., face of the cube) is and th.
More Optical Connection References
- Japan s Power Pole and Fiber Optic Cable Laying
- What is a laser diode manufacturer
- Price Inquiry for Mobile Optical Cables
- SC connector fiber optic active connector
- Compatible Low-Loss Optical Core Router Belgian Supplier
- Why do we need a distribution box
- Is the pigtail FC head round or square
- Aluminum Alloy Cable Management Frame Selection Guide